SYNTHETIC DATA GENERATION
How We Built a Synthetic Data Engine That Protects Privacy Without Losing Realism
Conventional data masking protects individual fields but leaves real records in use. Basic generators create realistic-looking values but lose the relationships that make data useful. Medoid AI built a synthetic data engine that generates entirely new, connected records, preserving the patterns and business logic of the original database without exposing a single real one.
Up to 98% evaluation score.
87% relationship accuracy.
70% faster training.
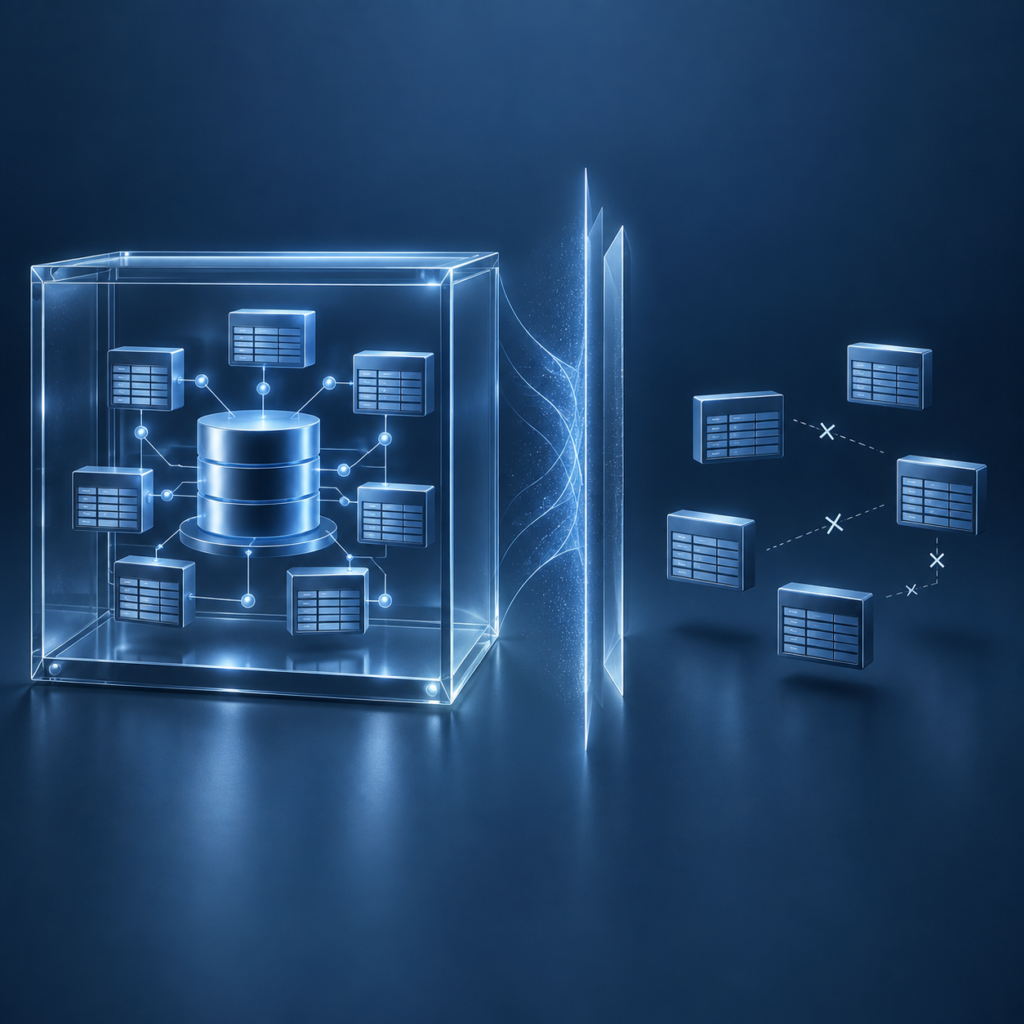
Organizations regularly need realistic data when real production data can’t safely be used, but most data isn’t simple, standalone records. A single customer, order, or claim is often spread across many connected database tables, and every version has to make sense when viewed as a whole.
Existing approaches forced a trade-off. Masking hides identifying details but still relies on copies of real records. Basic generators create believable individual values but lose the patterns, relationships, and business rules that made the original data useful in the first place, undermining confidence in anything built on top of it.
The system needed to learn from the real database, generate genuinely new records, preserve both obvious and hidden relationships, handle specialized data like names and emails correctly, and prove the result was trustworthy without ever duplicating sensitive information.
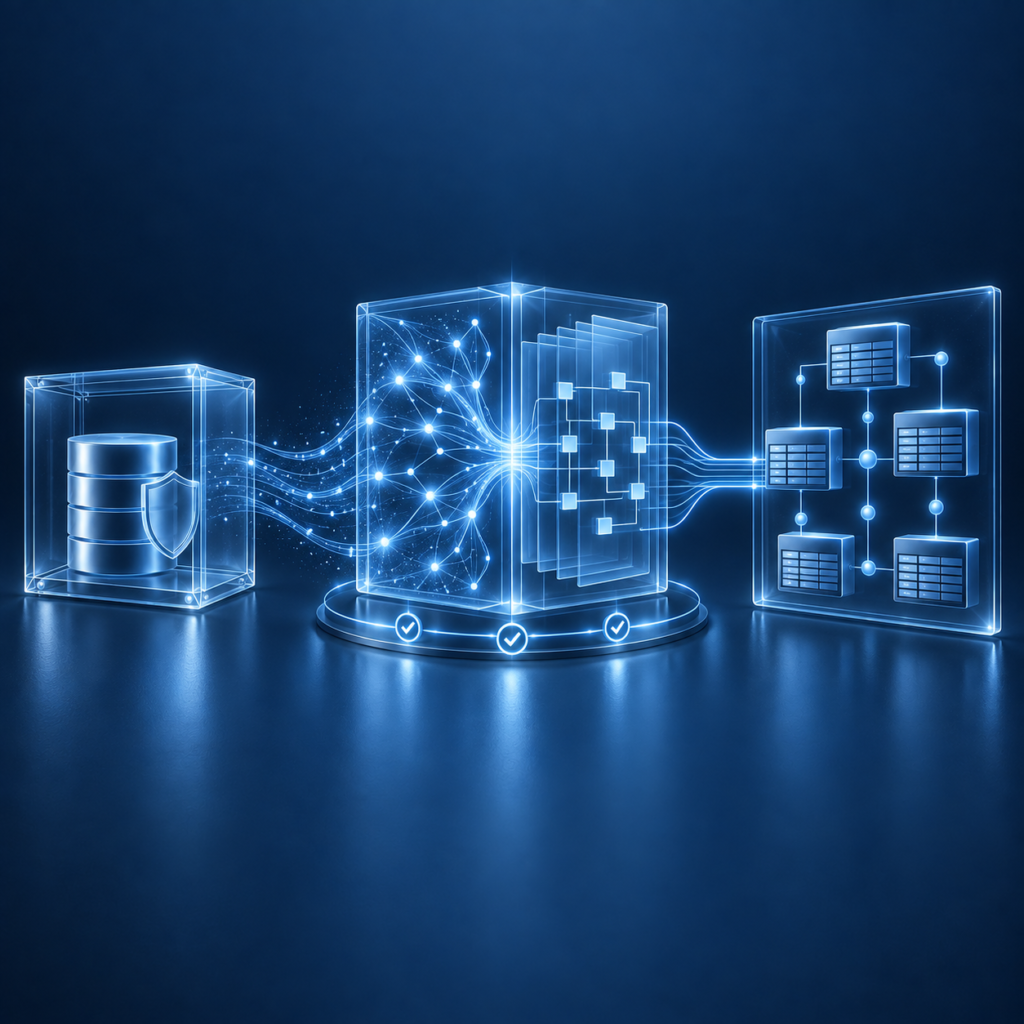
We balanced three priorities: privacy, realism, and reliability. Deep learning captured the patterns in the source data, while rule-based controls handled anything that needed an exact, predictable result. Every stage was tested against different database structures, with quality measurement built in from the start.
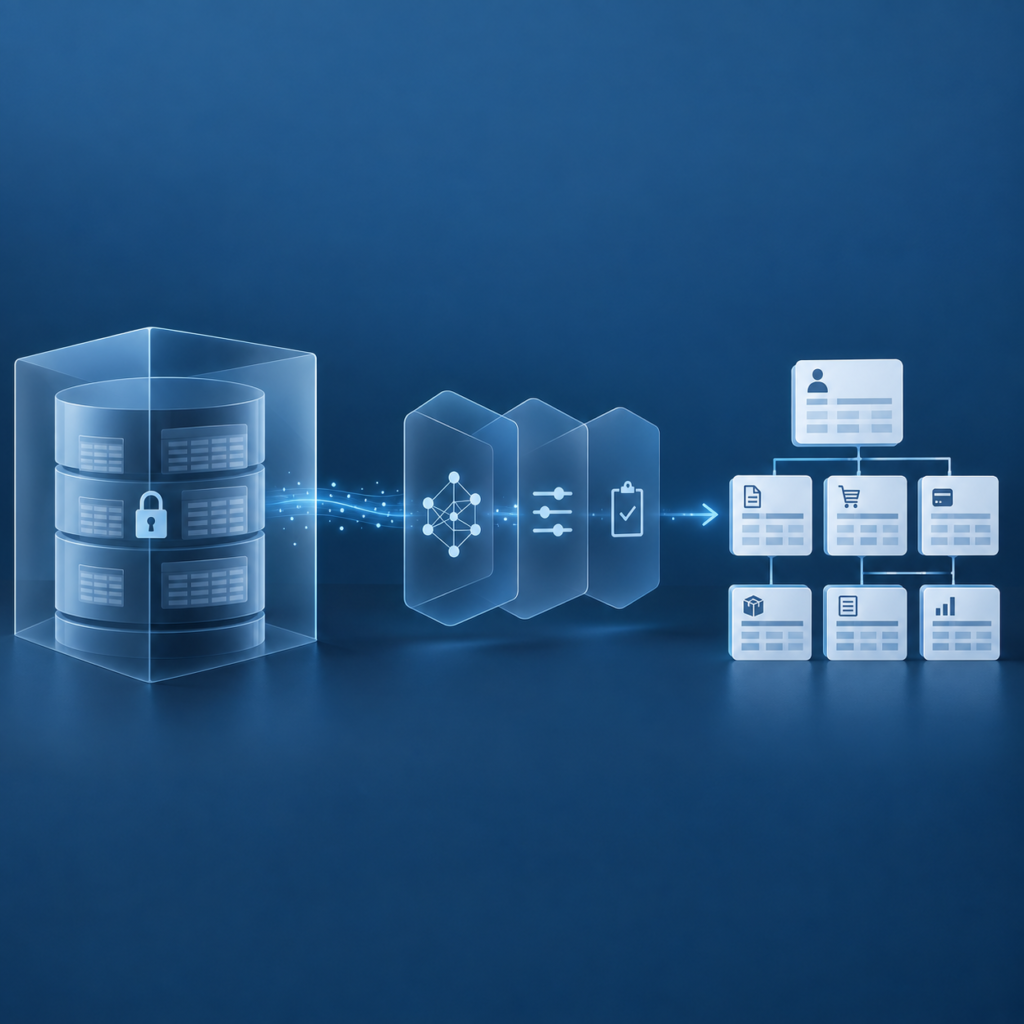
We designed and delivered an end-to-end synthetic data system that combines deep learning with purpose-built database logic. Rather than generating each table in isolation, the system first studies the full database, its structure, relationships, and rules, then builds new records in the correct order, starting with root records and adding the connected details that complete each entity.
- Learn how the data behaves. Deep learning models capture patterns within each table and the relationships between them.
- Builds connected records. New data is generated in the right order, with fresh identifiers and the links between tables intact.
- Handles specialized data correctly. Purpose-built models generate realistic names, emails, and IDs, while simpler rules handle dates and formatted values where a full model isn’t needed.
- Preserves business logic. Automated checks confirm that relationships and rules not directly visible in the database structure still hold true.
- Measure the result. An evaluation layer compares real and synthetic data on structure, relationships, validity, and how genuinely new the synthetic data is.
The system was delivered as a set of services inside the client’s existing cloud environment, so training, generation, and evaluation all run as repeatable tasks the client’s team can reuse and build on.
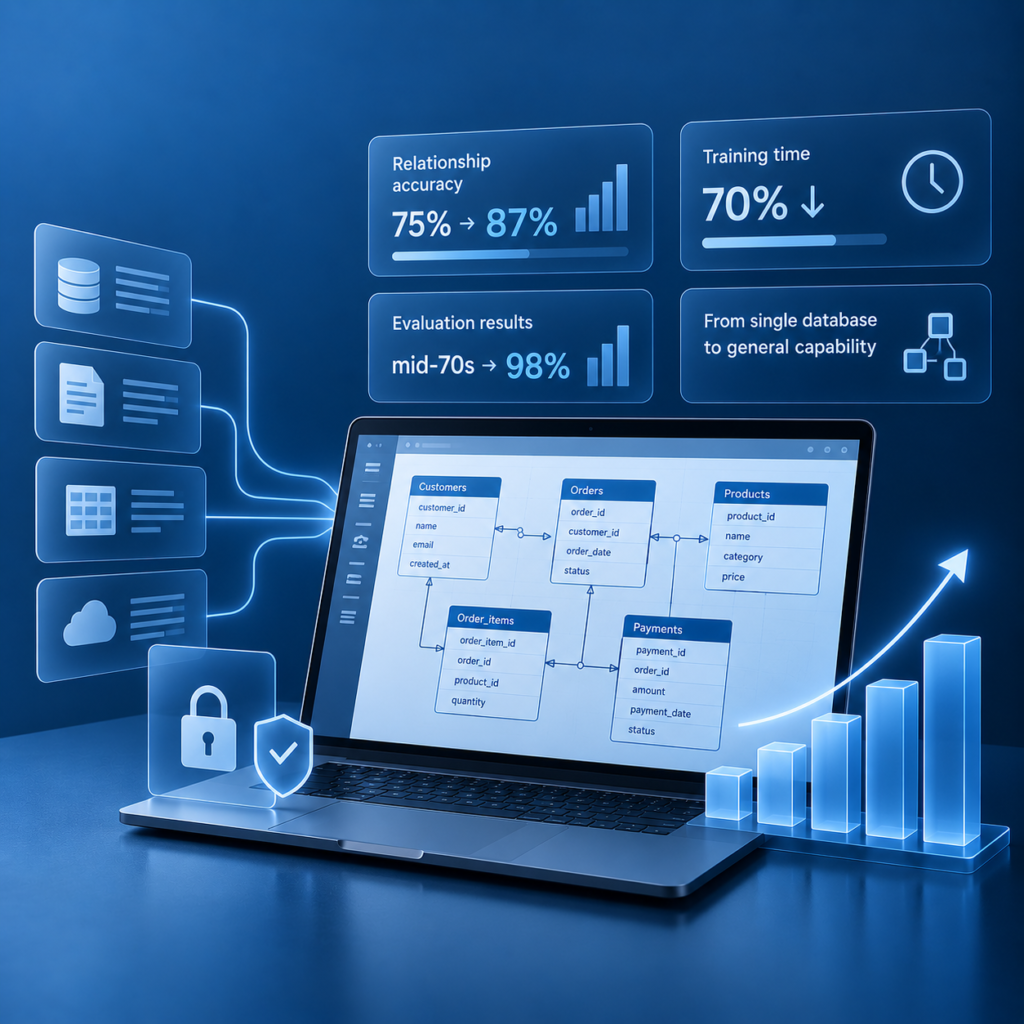
The client’s platform gained the ability to produce realistic, connected data without exposing real records, becoming a core part of their product, not a bolt-on feature. That strengthened their pitch to prospective customers with strict privacy and data-access requirements, and helped win new business.
Across six phases of development, the system evolved from working on a single small database to a general capability tested across many different data structures. Relationship accuracy rose from roughly 75% to 87%. A redesigned training method cut training time by roughly 70%. Across different database types, overall evaluation results ranged from the mid-70s to 98%.
The result: a repeatable way to generate realistic, connected data, with the evidence to prove its quality, not just assume it.